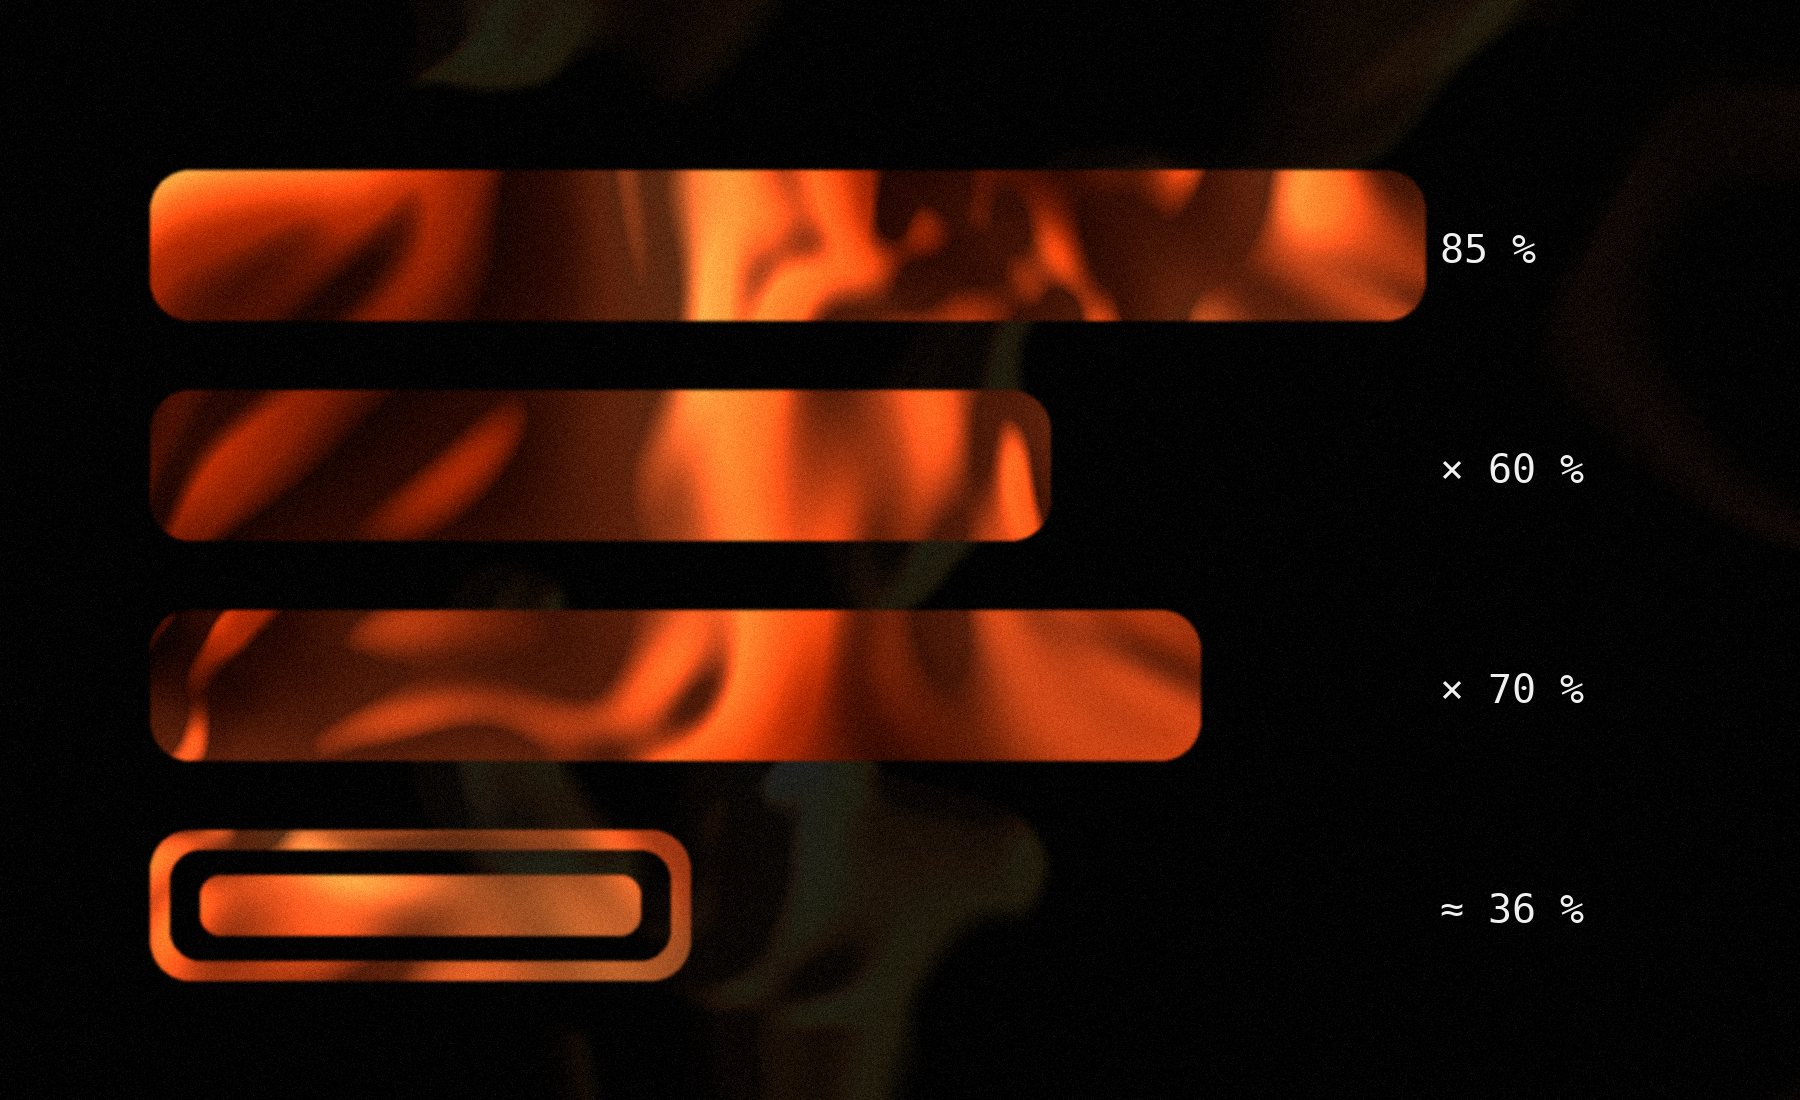
“85% faster at coding” - you hear figures like this a lot. They describe single tasks. What reaches the project is something else.
From task to project
Even on favourable assumptions, project impact lands far below the figure that gets quoted - because the three factors multiply.
Context readiness covers two things. First, what share of the knowledge a change needs is accessible to the AI - in code, tests, documentation and rules rather than only in developers’ heads. Second, how good that context is: how complete, how stringent and uniform, how free of contradictions. Classic code quality belongs here too: readability, clear structure, tests. Early studies show that AI breaks functionality less often on healthy code (Borg et al., 2026, preprint, vendor-affiliated authors).
Share of activity reflects that development is not only coding. There are ceremonies and meetings, alignment, ad-hoc tasks, preparation and follow-up, research. A lever on coding only acts on that share. Meetings are blocked time: nobody codes in them. AI helps with meetings mainly in preparation and follow-up - and for many rather spontaneous meetings there is little of either. In field studies, developers’ pure coding time is often only 11 to 21% (Meyer et al., 2017; Meyer et al., 2019; Kumar et al., 2025). The 70% in the example is therefore a deliberately very favourable choice. More on which part of the week can be reached at all: 30 minutes stay 30 minutes.
What the studies say about each factor
The example above is an illustration. For each of the three factors, though, there are studies from which a typical range can be derived:
Pure coding 11 to 21%; much more with understanding code, testing and debugging - program comprehension alone takes 58% of the time in one study (Xia et al., 2018)
Experiments from 2023 to 2025 measure 21 to 56% time savings (Paradis et al., 2024; Peng et al., 2023).
Only measurable indirectly: agents solve 15 to 18% of tasks in commercial repositories versus over 70% on common benchmarks (SWE-Bench Pro, 2025)
The result: a typical gross impact is more likely in single digits. The 36% from the example is even above the most favourable scenario the studies support. Context readiness is the least well evidenced factor - and that is exactly where the biggest lever is.
Every study through the same calculation
Studies on AI in development are hard to compare directly because they measure at different levels. The formula helps to normalise them - if you check which factors a study already contains:
- Lab experiment: a single task without a grown codebase. It measures only the efficiency lever. Share of activity and context readiness are added as ranges.
- Field experiment: real tasks in real codebases. Lever and context are already in the result. Only the share of activity is missing.
- Measurement at organisation level: this already is the project impact. Nothing more is calculated.
After normalisation, the field experiments land at around 5 to 14% - close to the typical value from the factor ranges. Lab values spread more widely because two unknown factors are added: a single lab figure says little about a project. An analysis of Git histories across more than 100,000 developer accounts finds, directly at organisation level, 15 to 20% more output net, with clearly smaller gains in complex existing code (Denisov-Blanch, 2025, talk, not peer-reviewed).
For Cui et al. we converted 26% more completed tasks into about 21% time savings.
A special case: experts in their own code
We deliberately leave one study out of the calculation. In early 2025, 16 experienced open-source developers worked on 246 real tasks in their own large repositories - randomly with or without AI. With AI they took 19% longer. Afterwards they still believed they had been 20% faster (METR, 2025).
That makes it unsuitable for the efficiency lever: the participants knew their code very well, were already fast without AI, and the tools date from early 2025. As a signal it is valuable - perceived and measured impact can be far apart.
From gross to net
The gross effect is not yet the time gained. Two kinds of effort come off it that do not exist without AI:
- Extra effort for quality and checking: AI drafts have to be read, tested and approved. More output means more review.
- Developing and maintaining the agentic systems: adapting them to one’s own processes, refining their behaviour, updates and migrations to new models and tools, maintaining the context.
On top come tool and model costs, building the engineering environment and enablement. The gain on the task is real. What reaches the project net depends on the work package, its share of the whole and this ongoing effort.
Our own practice experiment shows the same range: across 14 tickets, with partly estimated effort, effort dropped by around 93% for small tickets but only around 18% for the large, complex one (see the practice experiment).
And the time gained is more than a cost-cutting lever. In our projects it goes into what there was no time for before: further development, quality, topics that stayed in the backlog. Counting the effect only in hours saved measures the wrong thing - what matters is what the team achieves with the time it gets back. That is why we recommend putting the time gained into further topics - as a rule, it is the better investment. If you would still rather use the gain as a smaller team, that works too: as a service provider we then deploy our people in other projects, where their experience is in demand anyway.
What research says
We don’t rely on our own figures alone. Five findings from recent studies - including counter-evidence:
| Finding | Source | Evidence type |
|---|---|---|
| 22.7% of AI-introduced issues are still present in the latest version - across 302,600 verified AI-authored commits in 6,299 repositories | Liu et al., arXiv 2603.28592 (2026) | Observational, static analysis |
| Refactoring fell from 21% to 3.8% of changed lines; duplicated blocks +81% | GitClear (2026) | Longitudinal repository telemetry |
| Output roughly doubled - reviewer load roughly doubled too | Denisov-Blanch et al., arXiv 2607.01904 (2026) | Longitudinal, single company, preprint |
| 44% of tested code-generation tasks produced code with a detectable vulnerability; rate flat | Veracode (2026) | Controlled security benchmark |
| Specifications were associated with slightly more defects and more rework - read by the authors as a selection effect | Hill, SSRN (2026) | Observational, counter-evidence carried deliberately |
The brownfield reality
For an ordinary change in a system that has been running for years, an agent needs:
- the requirement in a testable form - often there is just a ticket, some prose and a conversation,
- the rules the change must respect - often only in the heads of long-standing team members,
- a way to build and run the system - often a setup kept working by hand,
- tests that show the change worked - often only where testing was easy.
Context readiness is not a fixed ceiling but an investment path. Tests, documentation, a reproducible build and explicit rules are the largest single lever.
Humans and machines: who does what?
Share of activity and context readiness limited projects long before AI. What is actually new is only the efficiency lever. So it seems natural to set up the calculation twice - once with human efficiency, once with machine efficiency - and compare. Share and context would then cancel out.
They do not, because both factors differ for humans and machines:
- Context: people carry tacit knowledge - why something was built this way, who decided what, what the client actually means. An AI only sees what is written down. The more of it lives only in people’s heads, the smaller the machine’s advantage.
- Share: not every activity suits both equally. Within what an AI does well, consultants with AI were 25.1% faster and delivered over 40% higher quality. On a task just outside that boundary they were 19 percentage points less likely to be right than without AI (Dell’Acqua et al., 2023). The boundary is not straight but jagged - and hard to see from the outside.
More AI is therefore not automatically better. A meta-analysis of 106 experiments shows: on average, humans and AI together perform worse than the better of the two alone. Gains occur more in tasks where something is created, and where the human alone is already strong. Losses occur more in decision tasks (Vaccaro et al., 2024). Trust has a downside too: in one study, developers with an AI assistant wrote less secure code - and more often believed it was secure (Perry et al., 2023).
Two common assumptions are not supported by the studies. Creativity is not purely a human advantage: in generative tasks the combination tends to help. And while an AI switches context without warm-up time, it does not process long context without loss - information in the middle of long inputs is used less well (Liu et al., 2024).
For the calculation this means: the gain does not come from AI making everything a little faster. It comes from a deliberate division of labour - the machine generates and searches, the human decides and checks. And every piece of knowledge that moves from people’s heads into code, tests and rules shifts the boundary of what the machine can take on.
Where things are heading
Individual studies are snapshots. Series that measure the same way every year say more. They show a widening gap: what the technology can do grows fast. What reaches the project has hardly kept pace so far.
The values come from task-length measurement (METR, 2025; METR, 2026), price trends (Epoch AI, 2026), the developer survey (Stack Overflow, 2025), official statistics (Destatis, 2025; EU: 8% to 20%, Eurostat, 2025) and a long-term repository analysis (GitClear, 2026, analytics vendor, no causal proof).
What holds today: capability and price develop exponentially, use and adoption double within a few years. At the same time approval and trust fall, and code gets cleaned up less often. The measured gain in the project stays in a narrow band.
| Outlook for 1 to 3 years | Confidence | Basis |
|---|---|---|
| Today's top performance will cost a fraction within about a year. Cost will rarely be the argument against AI | high | stable price trend over three years |
| Agents take on longer, connected tasks - from hours towards days | medium | extension of the trend so far; the measurement setup reaches its limit above 16 hours |
| This grows the share of activity the lever acts on | medium | our inference from trend and formula |
| The bottleneck moves to context readiness and checking: when more code is produced and trusted less, review and quality assurance become scarce | medium | our inference from the gap |
| A percentage for project impact in three years | not credible | no series measures project impact over time |
For the calculation this means: the efficiency lever will keep growing - but even today it was not the limiting factor. Those who build context readiness and checking now will take the progress of the next models with them. Those who don’t are buying faster tools for the same bottleneck.
What this means for buying
A range with stated conditions is more reliable than one percentage. Two fair ways: agree the AI effect as a range with the classic offer as fallback - or start together, measure and adjust.
On top come two models where the risk sits with us: a fixed price including AI - if it goes faster, we benefit; if it takes longer, it does not cost you more. Or a share of the business case: we work out together when the project pays off for you, deliver it and receive an agreed share of the savings when the result is right. The price then follows the value, not the hours.
For consulting, workshops and getting to know each other at the start, we also work on time and materials or with small fixed prices. We name the budget range we expect to land in - so the project stays flexible while goal and scope are still taking shape, without a large budget having to be released first. All models at a glance: Time and materials, fixed price or sprints?
When you measure, look not only at what gets faster but also at what becomes possible as a result: cleared backlogs, more tests, time for improvements. That is where the value shows most clearly.
